Are LLMs Becoming Idiots?
I worry about uncritical AI content finding its way back into training data: a reflection on source quality, not proof that every LLM is getting worse.
Written byIdir Ouhab
Follow Idir on X · ES/EN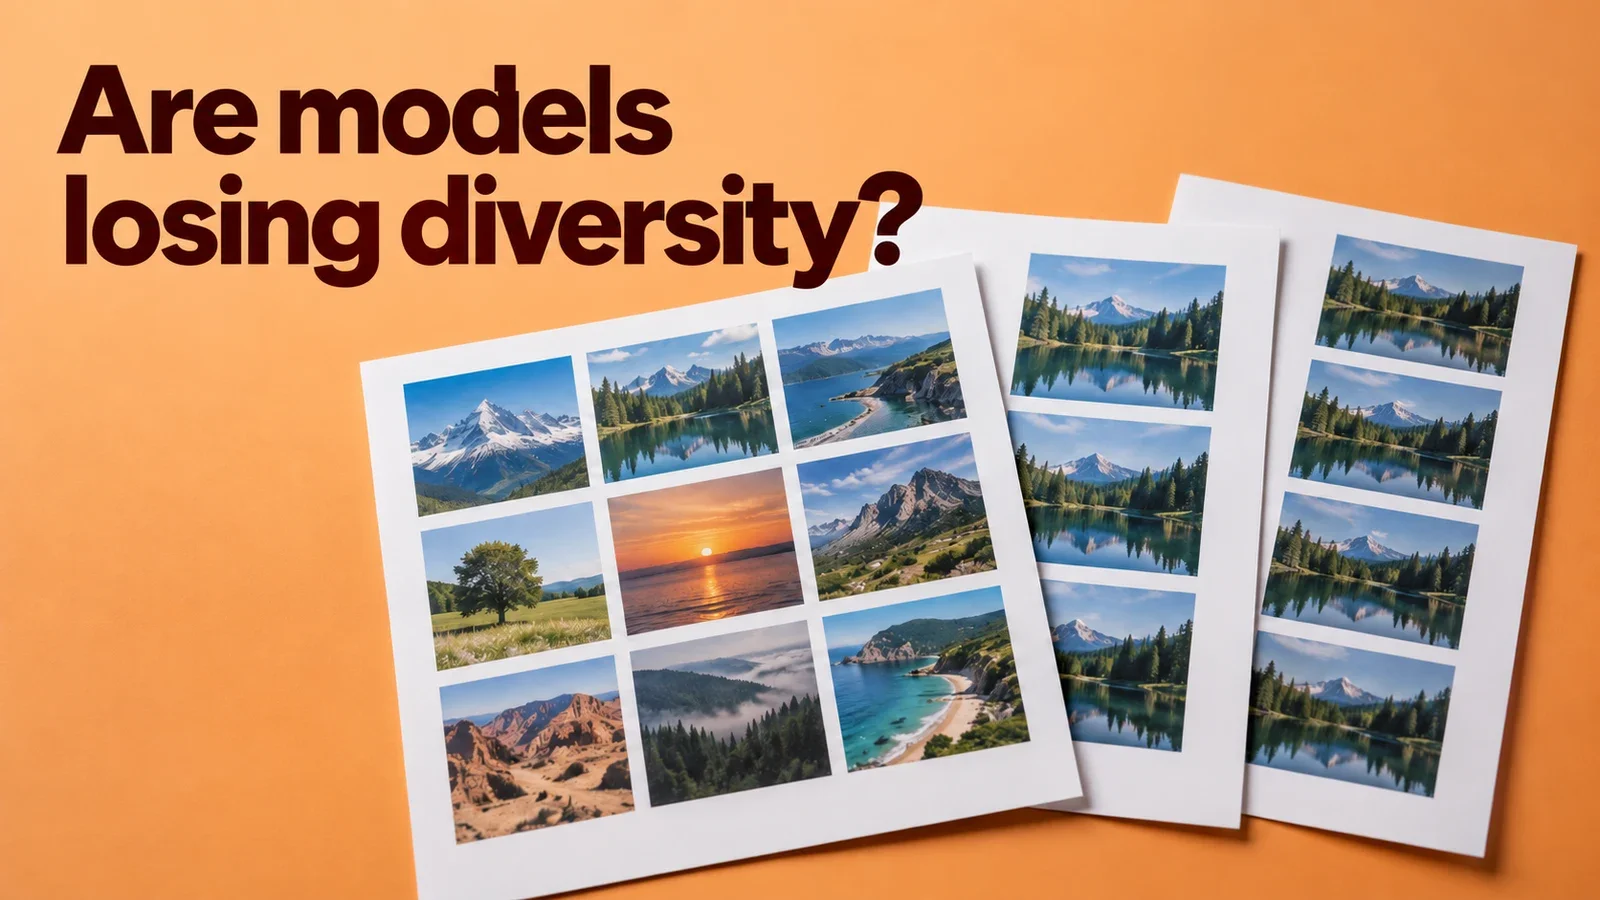
One of the best advances of the 21st century has been bringing Artificial Intelligence into our homes. No longer just to help us ask ChatGPT what the height of a poodle is, but to use it for slightly more useful tasks (not much more) like helping me do my job better.
But in this post I'm not here to talk to you about automation, but about the quality of the data used to train the now-famous LLMs. If you don't know what an LLM is, I recommend watching this video from Dot CSV before continuing.
😡🤬 The Damn Emojis 🤯🚀
How many emojis have suddenly appeared in LinkedIn posts, Facebook, and other social networks from pseudo-content creators?
How many of them do you think are AI-generated?
The emojis are my observation, not a detector of AI-written text. Counting them does not establish who wrote a post or whether it entered a training dataset. My concern is what happens if generated material is reused without checking its origin and quality.
AI training on AI
Imagine a hall of mirrors: a model generates a post, someone publishes it, and a later training dataset includes it. That is a possible feedback loop, not a verified account of what happens to every social post. Publication or search indexing alone does not show that a model was trained on it.
I call the risk digital autophagy. The research question is what happens when generated samples are repeatedly reused for training.
Model Collapse
That risk has a name: model collapse. I worry that training models on content generated by other models, without looking after data quality and diversity, could lead to 💩 results.
The research published in Nature in 2024 studies recursive training on generated data and shows how it can lose parts of the original distribution. It does not establish a universal rule that five generations cause a 50% loss of diversity.
Sources:
- Research commentary: Science Media Centre
The salvation of humankind
When I discussed this with Mandip Gosal, my colleague at n8n at the time, we considered spoken language as a possible source of original material.
That is a hypothesis from our conversation, not a proven solution to model collapse. Human conversations and their transcripts still need checks for provenance, accuracy and suitability before being used as training data.
HELP!
Two things you can do TODAY:
- Verify everything: Spend an extra 5 minutes checking that the data is correct.
- Contribute your unique experience: AI hasn't lived your experience, use it.
The problem isn't using AI, it's using it without critical thinking.
Discussion
Comments
No published comments