These are my personal views and do not represent OpenAI.
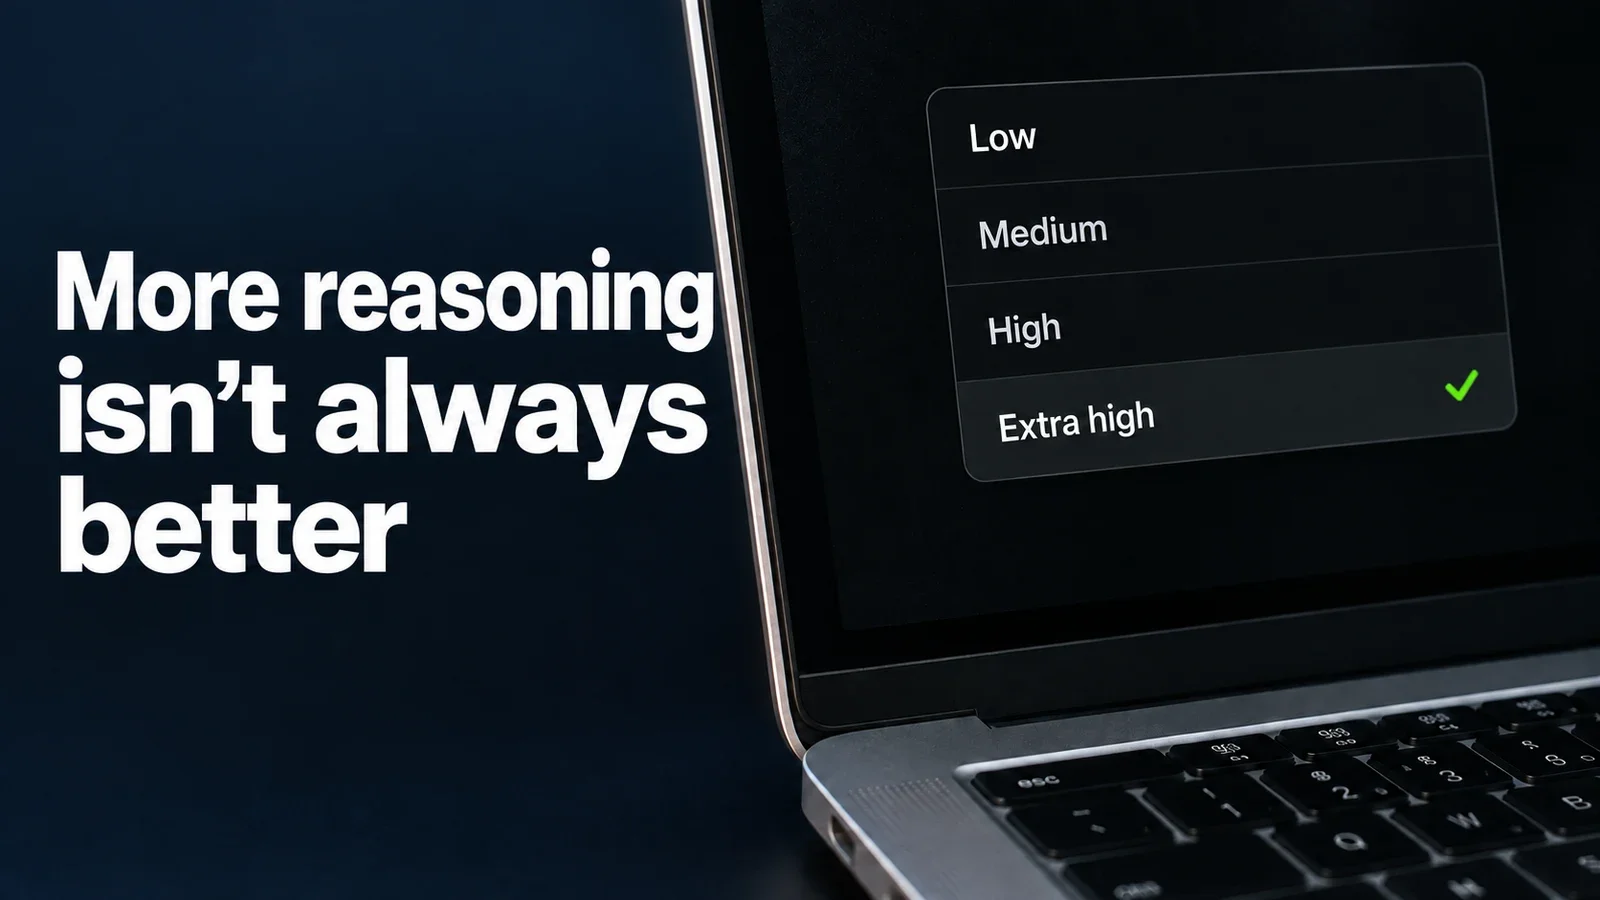
You see extra high and switch it on, just to be safe. After all, who wants to choose medium and wonder whether they’re leaving some of AI’s potential on the table?
Over the past few months, I’ve started to worry that reasoning effort is becoming the AI equivalent of “just give me the best one.” We turn it up for everything and assume the answer will be better.
The problem is, we might end up paying more for a worse answer.
Why more thinking can mean fewer correct answers
If the model is more capable and I give it more time, surely it will produce a better answer. Put that way, it sounds perfectly reasonable. It’s a machine, after all.
But how many of us have walked out of an exam knowing that another hour staring at the question wasn’t going to help?
OpenAI showed with o1 that giving models more compute for reasoning improved their performance on difficult problems. Here’s the o1 research, if you can be bothered to read it.
Still, choosing a more capable model and increasing its reasoning effort are two different decisions. With the second, you’re using the same model and giving it more room to explore possibilities and reconsider its answers.
And reconsidering an answer doesn’t necessarily mean improving it. The model might introduce a bad assumption or start paying attention to something it should have ignored.
That’s exactly the kind of behavior described in Inverse Scaling in Test-Time Compute. Some models found the straightforward solution, then talked themselves out of it, got tangled up in irrelevant details, and ended up getting the answer wrong.
In one test involving counting two objects surrounded by nonsensical code, Claude Opus 4 went from almost perfect accuracy to around 80% as reasoning increased.
It needed to count to two. It got carried away.
To be fair, OpenAI o3 improved with more effort on that same test. The effect wasn’t universal, and these tests were designed to probe specific failure modes.
What about high and extra high?
The GPT-5.5 guidance warns that increasing reasoning effort can reduce quality when instructions conflict, stopping criteria are unclear, or tool access is too open-ended. The model can end up searching unnecessarily or overthinking. That is a reason to evaluate the setting on your tasks, not to assume that high effort is always worse.
And yes, if you turn reasoning all the way up and get a worse answer, you still get billed for the API call.
We’ve been here before with context windows
This reminds me of the race to have the biggest context window. And I’m talking about less than a year ago.
Being able to fit more information into a model’s context doesn’t mean it will use that information well.
Lost in the Middle found that the models tested could become less accurate when relevant information was buried in the middle of a long context. That is a reminder to evaluate how a system uses context, not just how much it can accept. The study does not establish why a particular product introduced compaction.
How to choose a reasoning level
Having different models and reasoning levels lets you match the resources to the job. You don’t need to test every possible combination.
Here is my starting heuristic for the models available when I wrote this, not a benchmark or an official task-by-task recommendation. Check it against your own examples. The model names are documented in OpenAI’s catalog: Luna, Terra, Sol and Astra.
| Use case | Model | Reasoning |
|---|---|---|
| Extracting data, classifying information, and summarizing text | GPT-5.6 Luna | Low |
| Rewriting text and writing simple scripts | GPT-5.6 Luna | Low |
| Everyday coding, reports, and spreadsheets | GPT-5.6 Terra | Medium |
| Comparing sources and preparing proposals | GPT-5.6 Sol | Medium |
| Complex debugging and architecture decisions | GPT-5.6 Sol | High |
| In-depth research across multiple sources with conflicting information | GPT-6 Astra | High |
Turn up the reasoning when you can see what it improves. Your bill doesn’t need any help going up.
Discussion
Comments
No published comments